Run gh-30319440655-1
- Date (UTC):
2026-07-28 01:09:38Z - Benchmark:
a692fe4f972a7c8007558e1cecf8a08e - Timeout:
0.5h - Target:
scfuzzbench/aave-v4-scfuzzbench@3f1db8ad1a - Benchmark type:
property - Instances:
1×c6a.8xlargeper fuzzer - Harness:
scfuzzbench/scfuzzbench@41025567e3
Trial run
Warning — trial run. This benchmark was executed with fewer than 10 instances per fuzzer and/or a time budget shorter than 24h. Results from trial runs are meant for debugging purposes and are not valid for extracting conclusions across different fuzzers.
Charts
Report
Fuzzer Benchmark Report (from bug-count CSV)
- Time budget: 0.50h
Warning — trial run. This benchmark was executed with fewer than 10 instances per fuzzer and/or a time budget shorter than 24h. Results from trial runs are meant for debugging purposes and are not valid for extracting conclusions across different fuzzers.
Executive summary
This report is derived solely from cumulative bugs-found over time across repeated runs per fuzzer. It emphasizes robust, distribution-based metrics (median/IQR, success rates, time-to-k) and shape-based behavior (plateau time, late discovery share) instead of single-run time-to-first-bug.
Bugs found at fixed time budgets (median [IQR])
| Fuzzer | Runs | 0.5h |
|---|---|---|
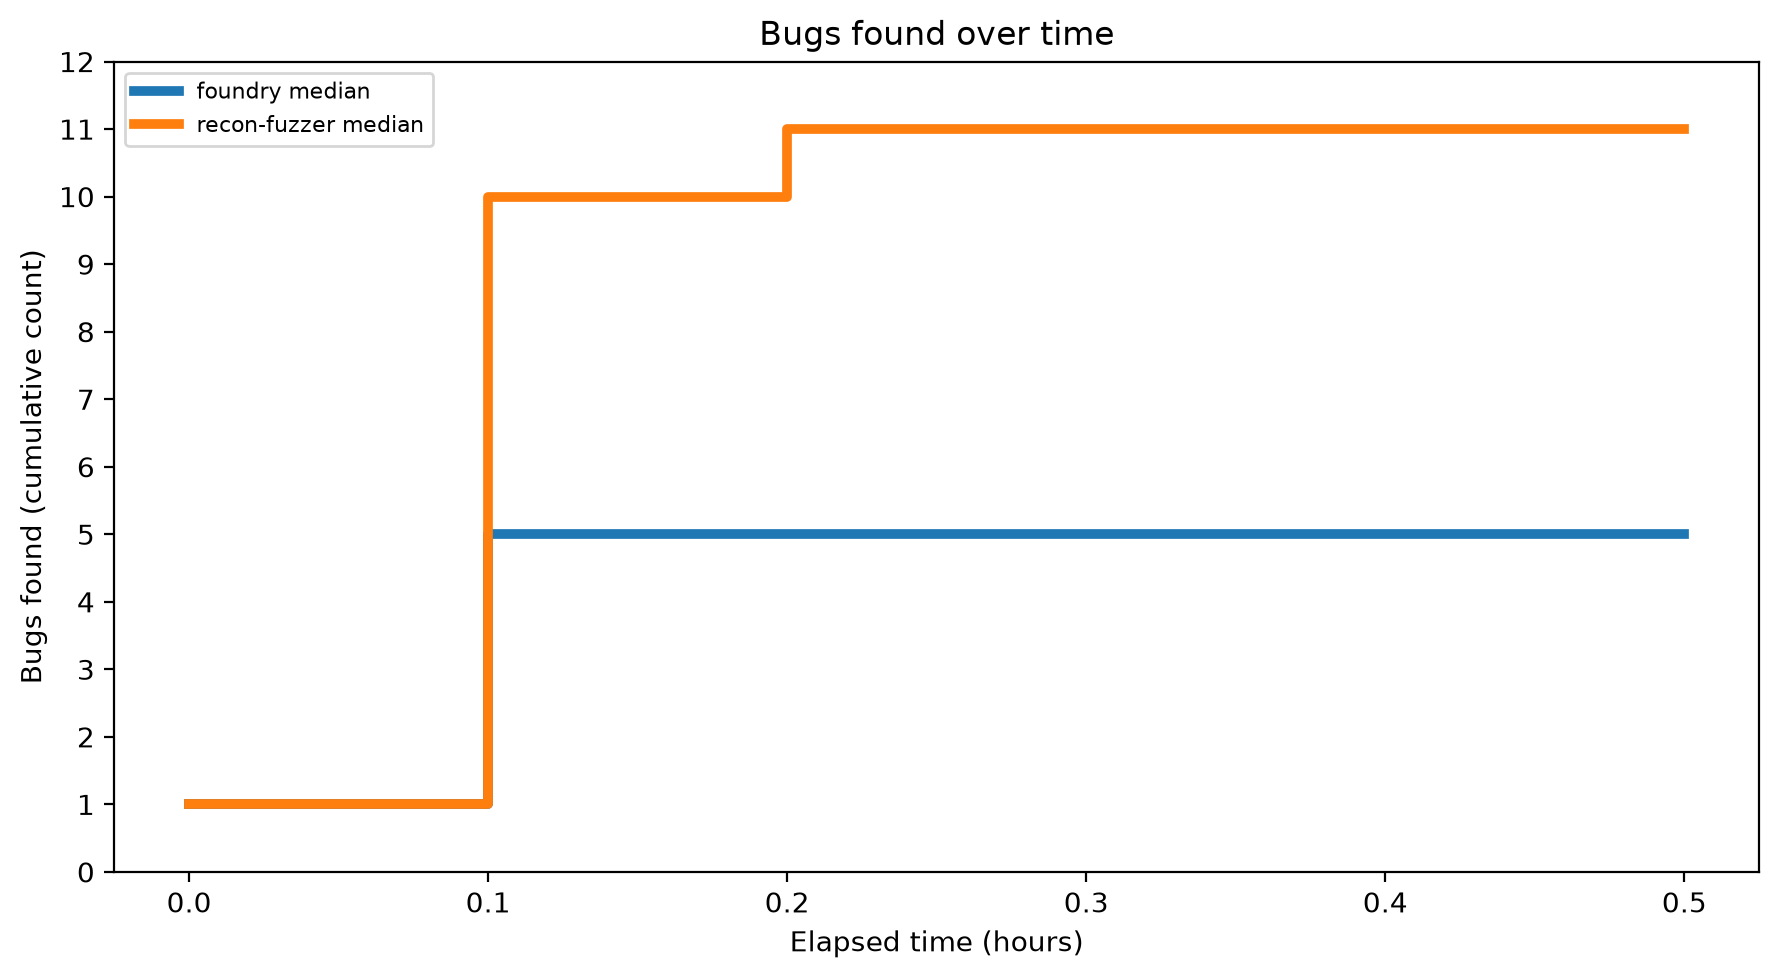
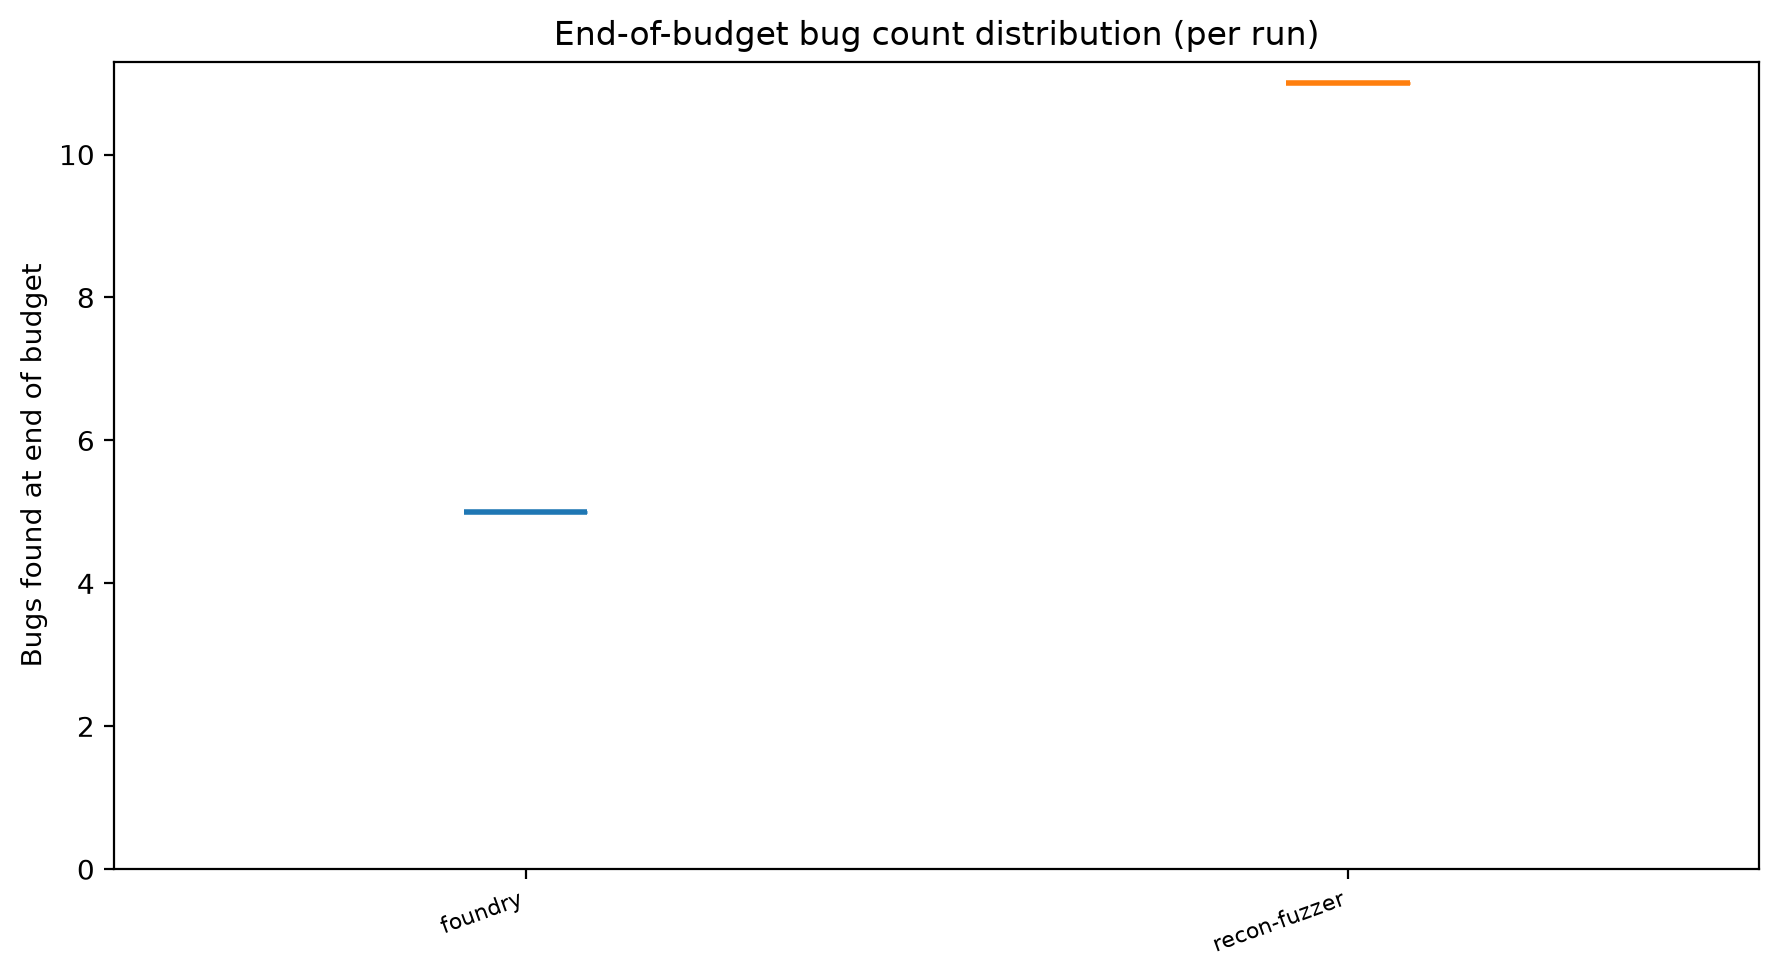
| recon-fuzzer | 1 | 11 [11,11] |
| foundry | 1 | 5 [5,5] |
Overall metrics
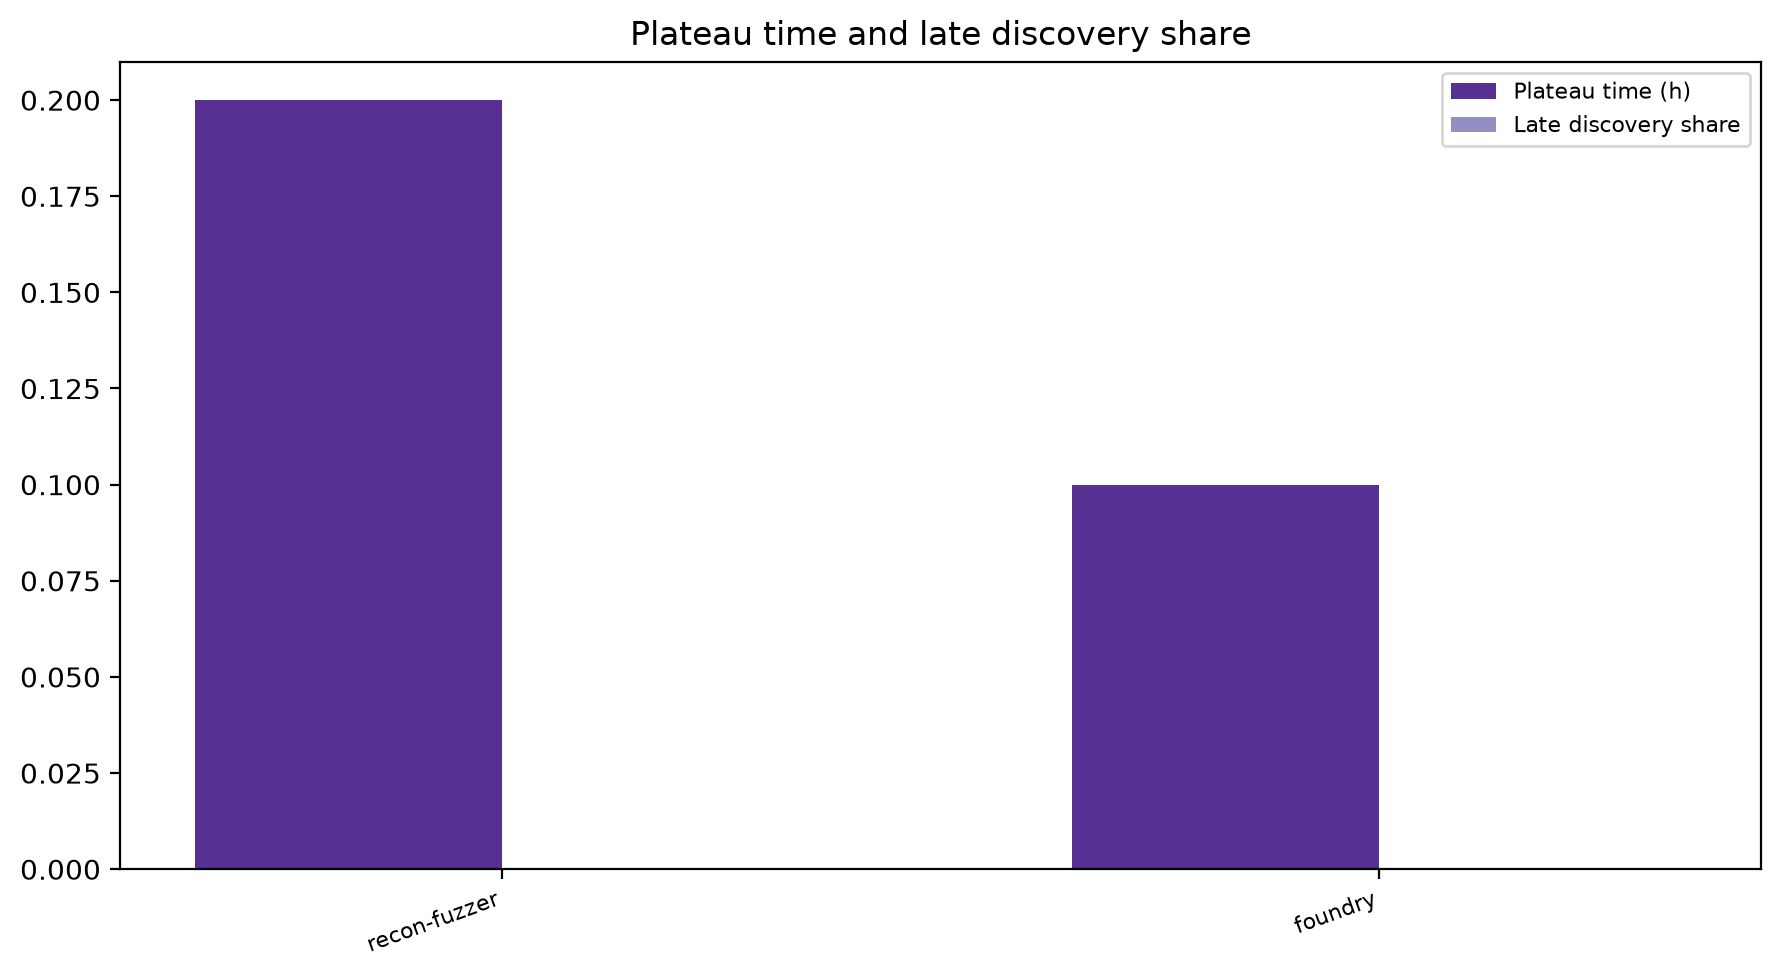
| Fuzzer | AUC (norm) | Plateau time | Late discovery share | Final median | Final IQR |
|---|---|---|---|---|---|
| recon-fuzzer | 0.800 | 0.20h | 0.000 | 11 | 0.00 |
| foundry | 0.382 | 0.10h | 0.000 | 5 | 0.00 |
Milestones: time-to-k and success rates
| Fuzzer | time-to-1 (p50) | time-to-3 (p50) | time-to-5 (p50) | reach-1 rate | reach-3 rate | reach-5 rate |
|---|---|---|---|---|---|---|
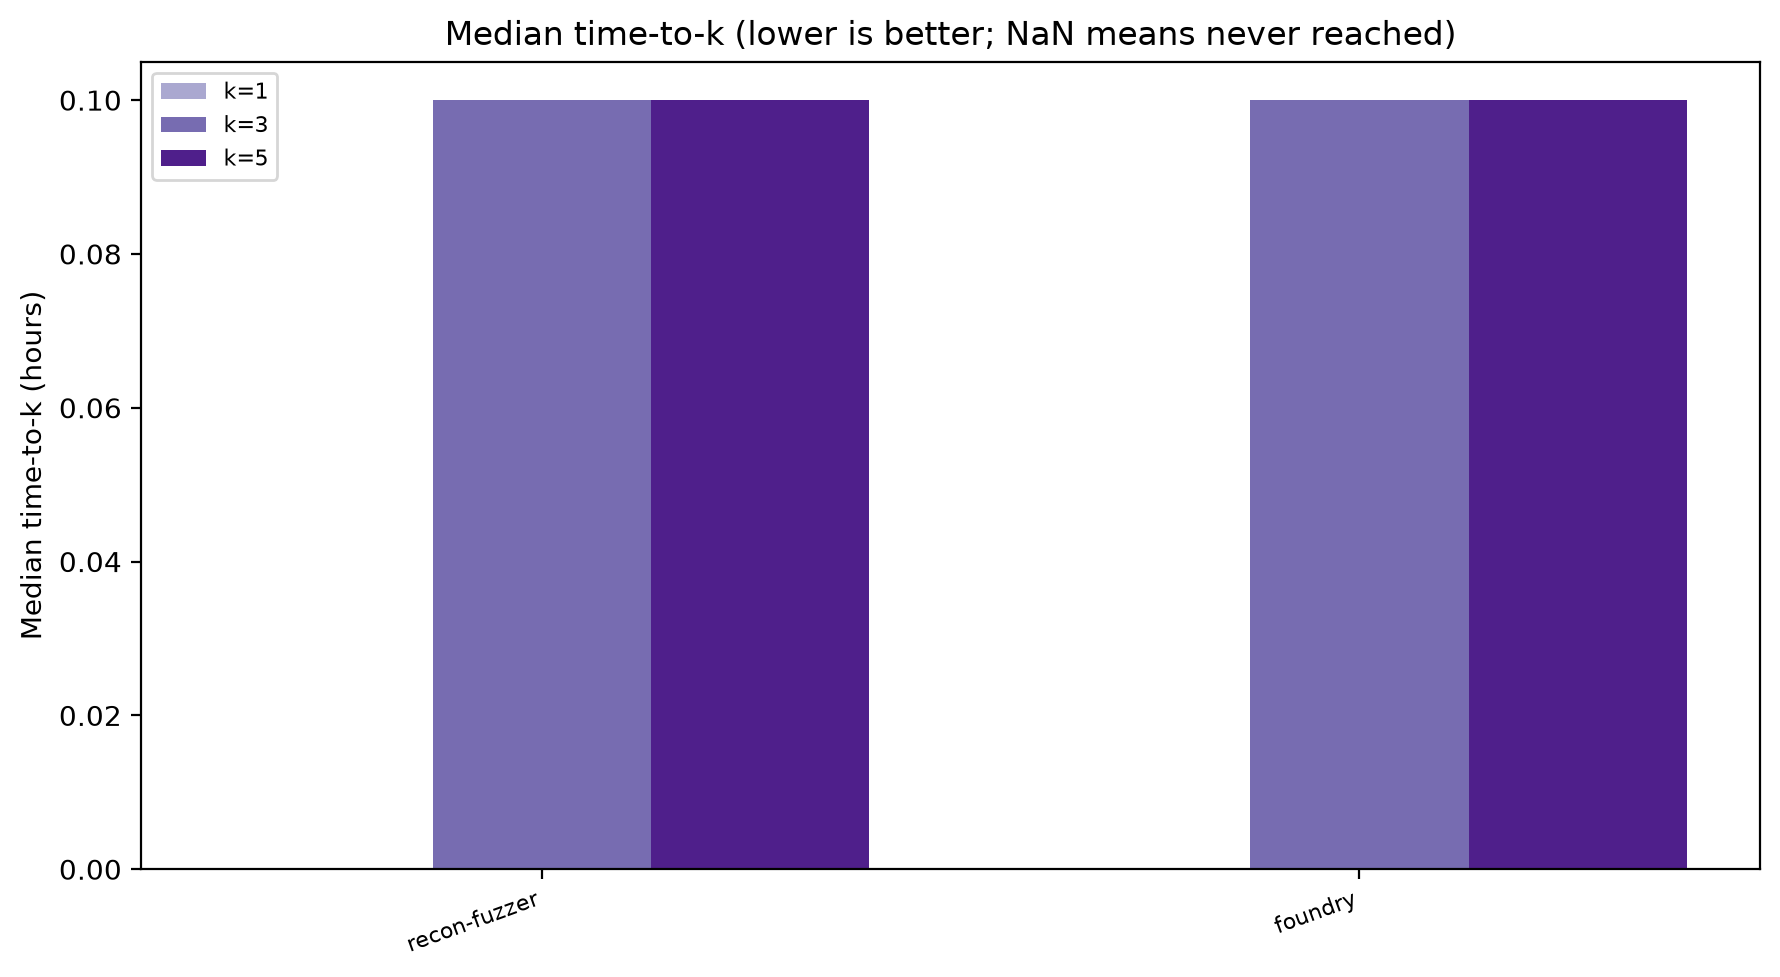
| recon-fuzzer | 0.00h | 0.10h | 0.10h | 100.0% | 100.0% | 100.0% |
| foundry | 0.00h | 0.10h | 0.10h | 100.0% | 100.0% | 100.0% |
Throughput metrics (if supported by log format)
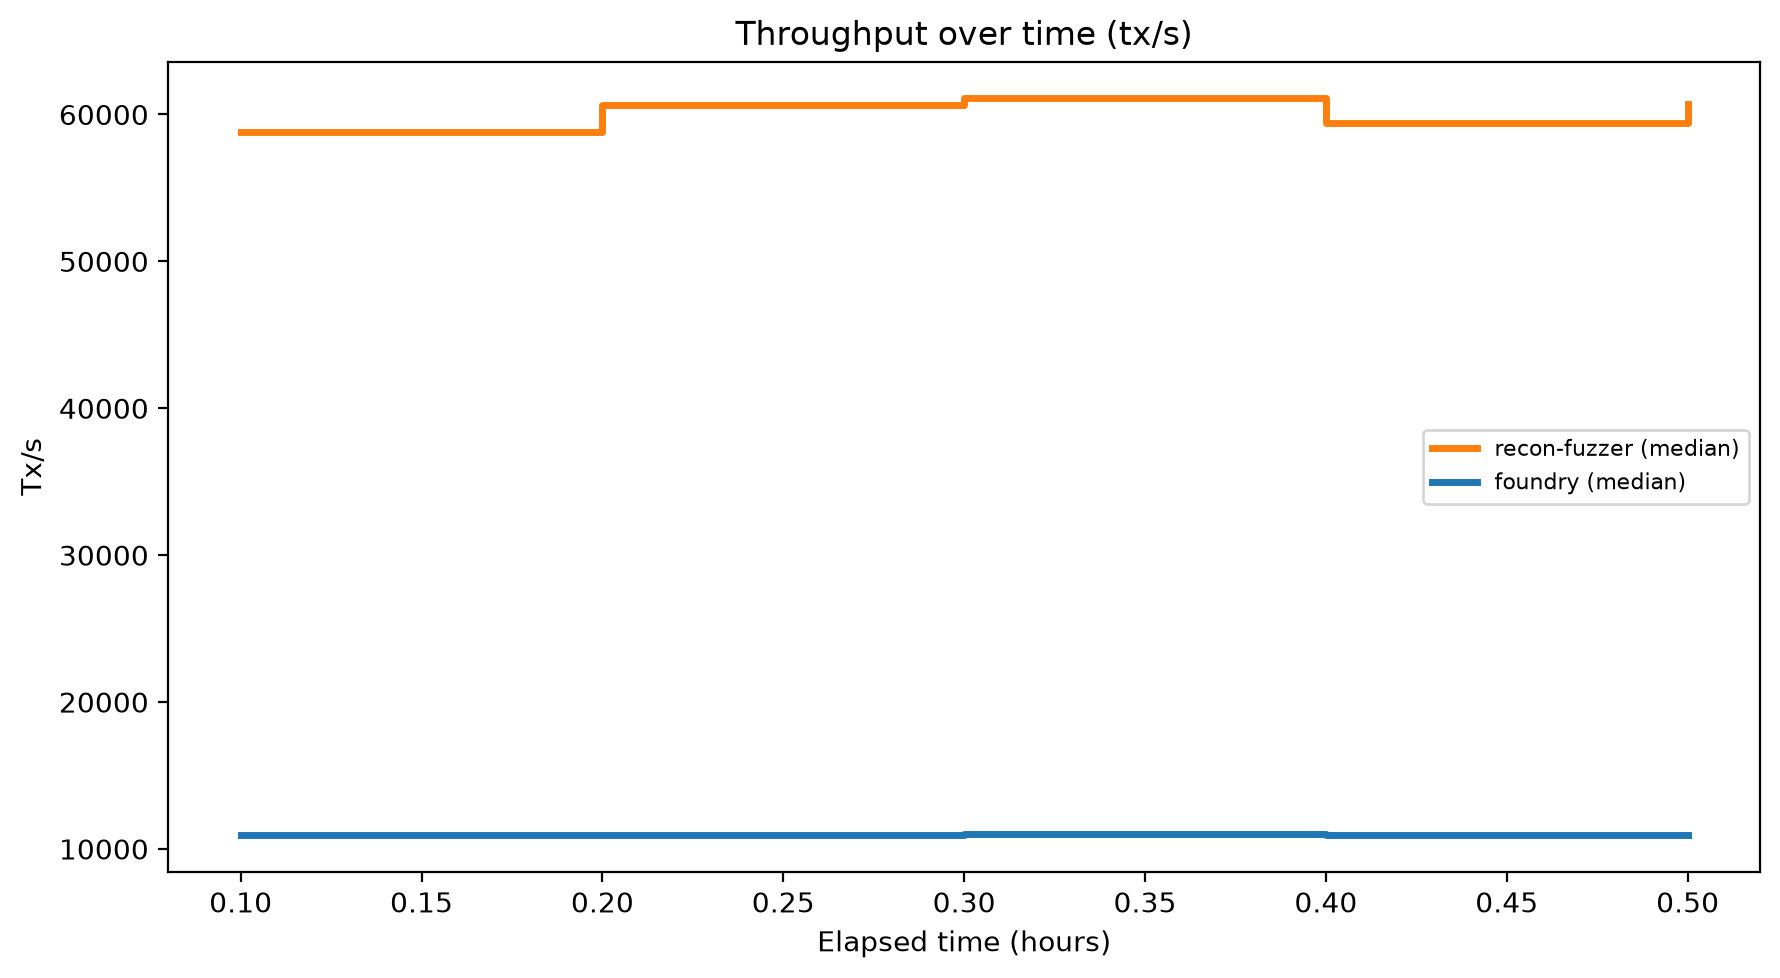
Values are run-level rates aggregated per fuzzer; n/a indicates the parser could not recover that metric from logs.
| Fuzzer | Runs | Tx/s runs | Tx/s p50 [p25,p75] | Gas/s runs | Gas/s p50 [p25,p75] |
|---|---|---|---|---|---|
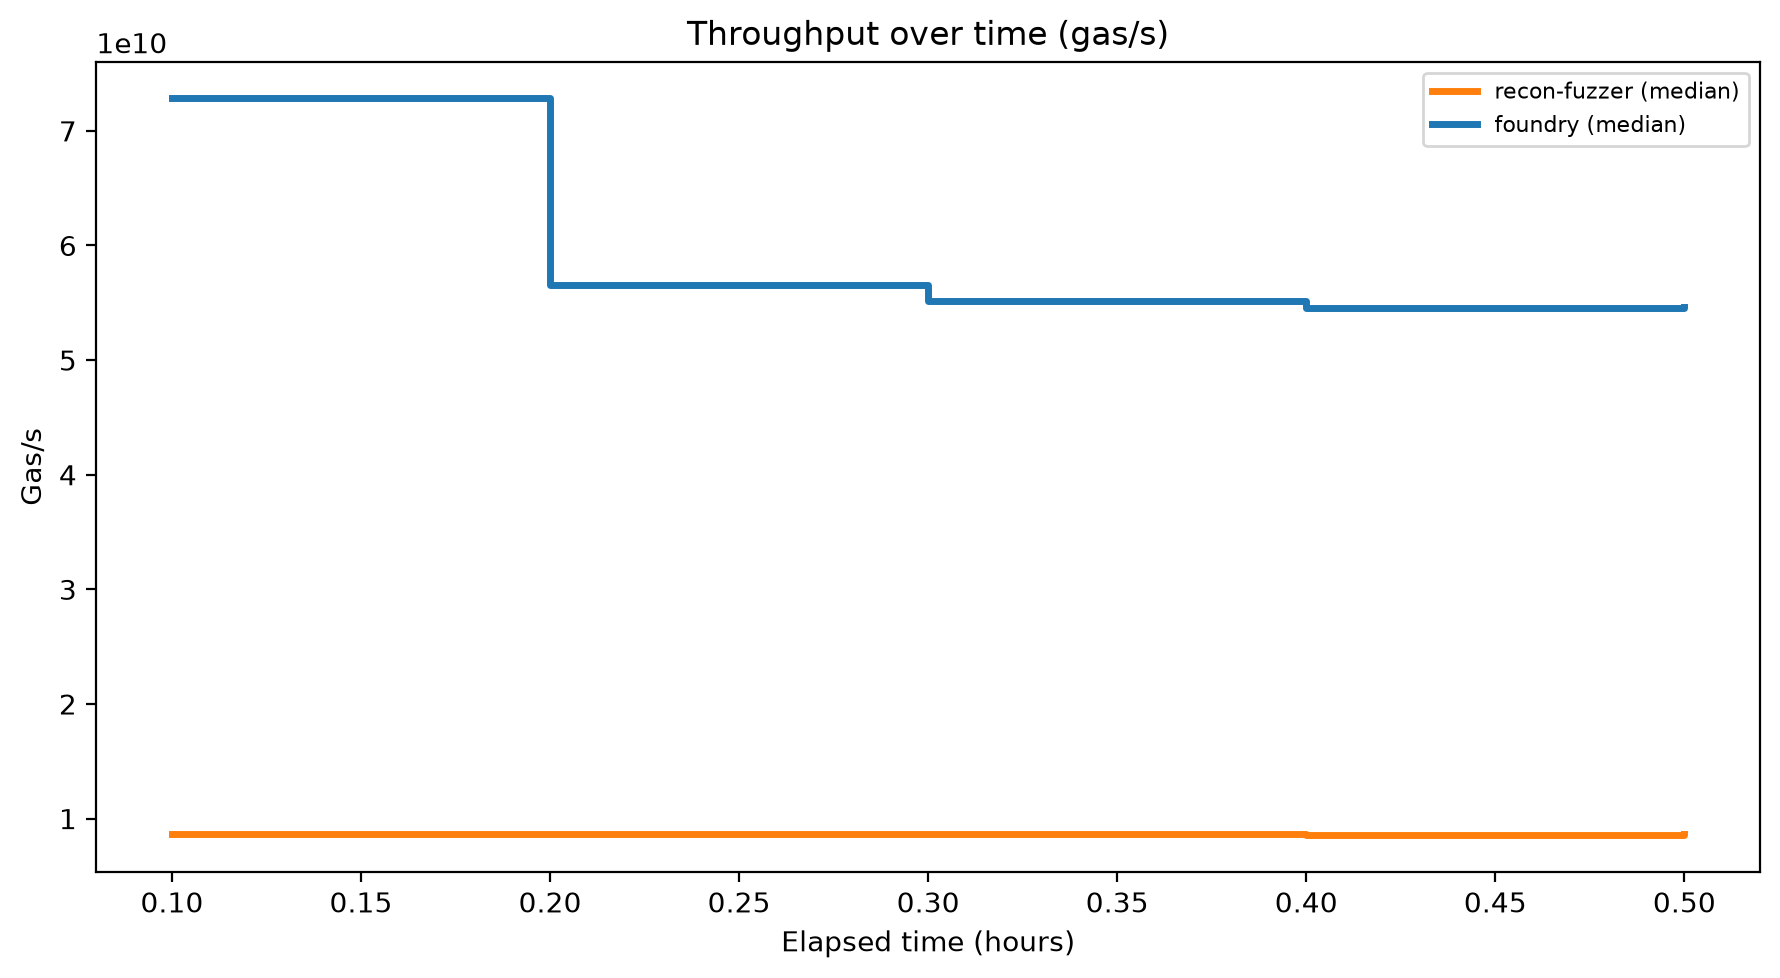
| recon-fuzzer | 1 | 1 | 60707.67 [60707.67,60707.67] | 1 | 8628842668.00 [8628842668.00,8628842668.00] |
| foundry | 1 | 1 | 10969.53 [10969.53,10969.53] | 1 | 54653701039.52 [54653701039.52,54653701039.52] |
Progress metrics from logs (fuzzer-specific proxies)
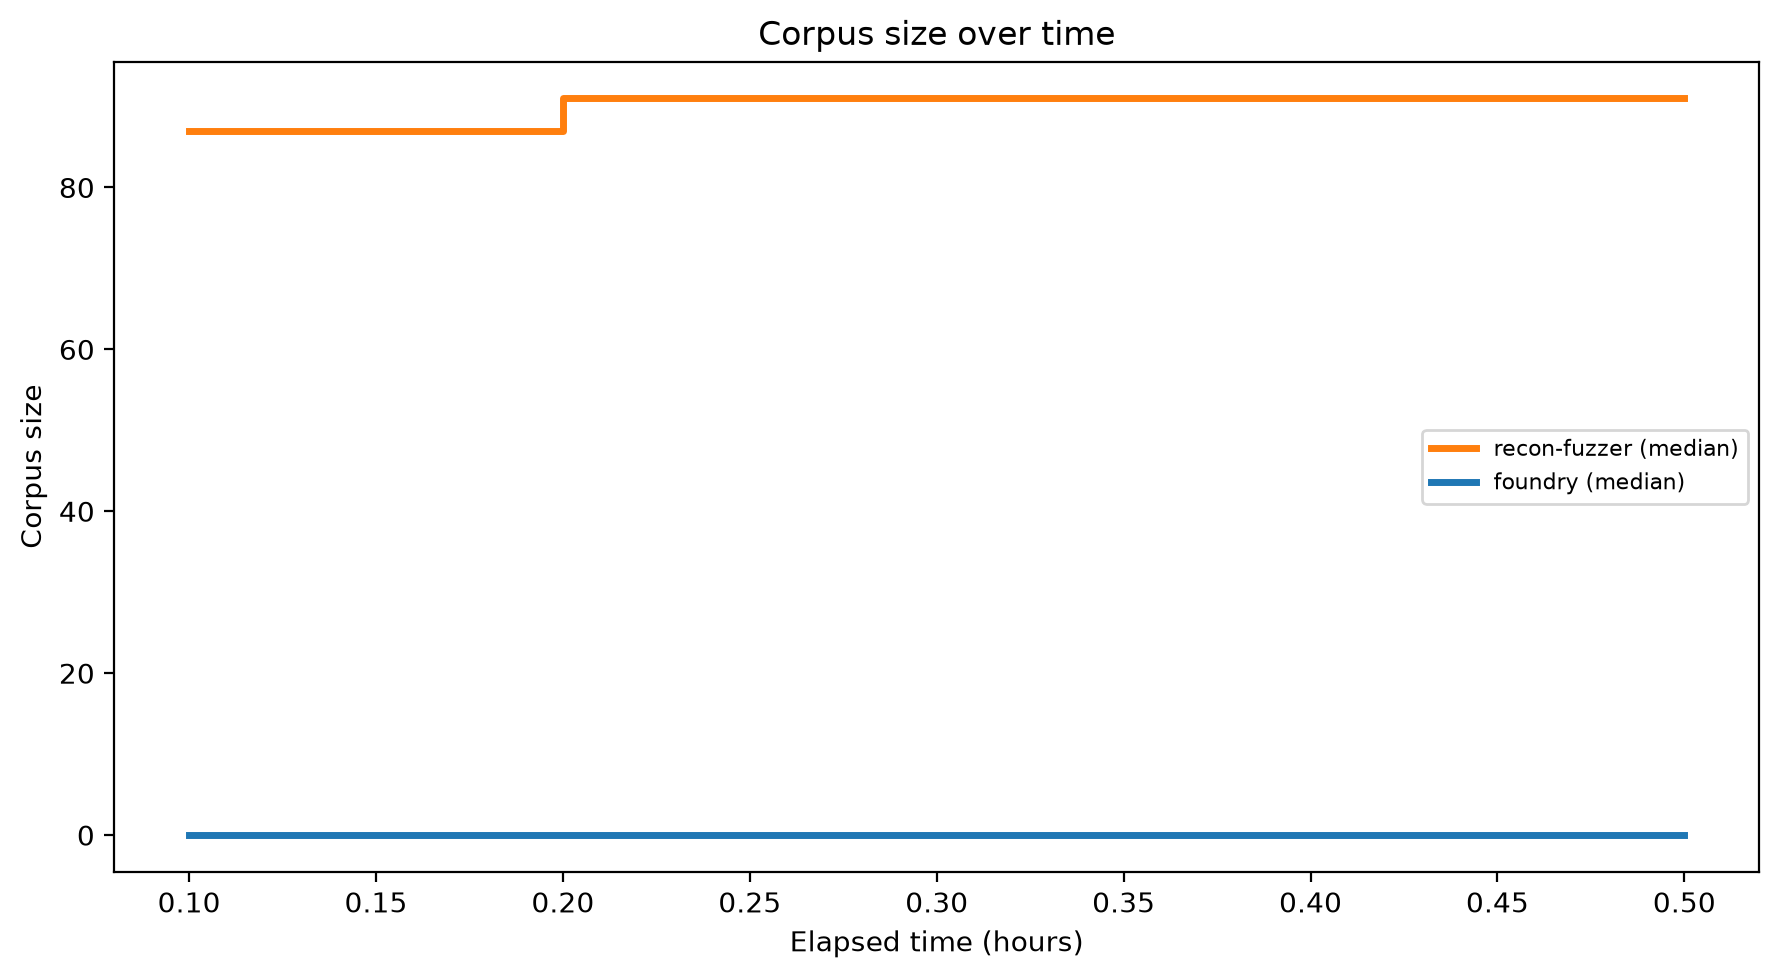
Sequence-rate and corpus values are parsed from native progress output and are useful for within-tool trend context.
| Fuzzer | Runs | Seq/s runs | Seq/s p50 [p25,p75] | Corpus runs | Corpus p50 [p25,p75] |
|---|---|---|---|---|---|
| recon-fuzzer | 1 | 0 | n/a | 1 | 91.00 [91.00,91.00] |
| foundry | 1 | 0 | n/a | 1 | 0.00 [0.00,0.00] |
Function selector sanity checks
Counts are occurrences in unique saved corpus sequences, not runtime execution frequencies The complete per-instance distribution is in selector_distribution.csv; selector_summary.json preserves statuses and provenance.
- Expected-set status: unavailable (0 selector(s))
- Expected-set provenance: peer-consensus heuristic: observed in every available corpus for at least two independent evidence families (Echidna and Recon count as one related typed-corpus family); not benchmark ground truth
| Fuzzer | Status | Instances with telemetry | Saved-corpus calls | Unique selectors |
|---|---|---|---|---|
| foundry | unavailable | 0/1 | 0 | 0 |
| recon-fuzzer | available | 1/1 | 8927 | 32 |
Most common saved-corpus selectors
| Fuzzer | Selector | Function | Calls | Share |
|---|---|---|---|---|
| recon-fuzzer | 0xdfbe4d80 | iSpoke_repay_ASSERTION_REPAY_DOS(uint256,uint256) | 476 | 5.33% |
| recon-fuzzer | 0xca2664f9 | iSpoke_setUsingAsCollateral(uint256,bool) | 361 | 4.04% |
| recon-fuzzer | 0xae22f4b8 | iAaveOracle_setPrice(uint256,uint256) | 355 | 3.98% |
| recon-fuzzer | 0xb722c6ed | iHub_updateAssetConfig(uint256,(address,uint16,address,address),(uint16,uint32,uint32,uint32)) | 354 | 3.97% |
| recon-fuzzer | 0x4896f9c3 | iHub_updateSpokeConfig(uint256,uint256,(uint40,uint40,uint24,bool,bool)) | 350 | 3.92% |
| recon-fuzzer | 0x5c9d5cb7 | iSpoke_supply_ASSERTION_SUPPLY_DOS(uint256,uint256) | 335 | 3.75% |
| recon-fuzzer | 0xf9f2ec54 | iSpoke_borrow(uint256,uint256) | 306 | 3.43% |
| recon-fuzzer | 0xf24a44c9 | assert_canary_ASSERTION_CANARY(uint256) | 299 | 3.35% |
| recon-fuzzer | 0x77494a8e | invariant_hubAddedSharesMatchesSpokeSum() | 296 | 3.32% |
| recon-fuzzer | 0x50fb9ec5 | invariant_totalBorrowedSharesMatchesSpokeSum() | 292 | 3.27% |
Selector telemetry limitations
- No expected selector set was available: the peer heuristic requires corroboration from every available instance in at least two fuzzer families
- i-0b7b9247f741264e6-foundry-git-02c05d9: Foundry selector distribution is unavailable because no persisted corpus was present; failure-event selectors are intentionally not used as a distribution
Statistical comparison (Mann-Whitney U and Vargha-Delaney A12)
Pairwise Mann-Whitney U tests and Vargha-Delaney A12 effect sizes on end-of-budget bug counts. The tests are two-sided, with Bonferroni correction applied for 0 comparison(s). Significance level: alpha = 0.05.
Warnings:
- One or more fuzzers have fewer than 5 runs. Statistical power may be limited.
- Skipping recon-fuzzer vs foundry: fewer than 2 runs.
Note: A12 is the probability that a randomly selected Fuzzer A run has a higher final bug count than a randomly selected Fuzzer B run, counting ties as half. Values above 0.5 favor A, values below 0.5 favor B, and 0.5 means equal tendency. Magnitude thresholds by distance from 0.5 are negligible (<0.06), small (<0.14), medium (<0.21), and large (>=0.21). Small sample sizes (fewer than 5 runs) reduce statistical power. A12 and its magnitude label are descriptive; the thresholds are rules of thumb. Neither the effect size nor statistical significance establishes practical importance, causation, or performance beyond the observed runs.
Shape-based interpretation (rules of thumb)
- Fast-start / early-plateau: high early checkpoint median + early plateau time + low late discovery share.
- Steady: moderate AUC, later plateau, consistent improvements across checkpoints, moderate variance.
- Slow-burn / late-surge: low early checkpoints but high late discovery share and later plateau time; often higher final median.
Limitations
- Core count-based charts use normalized event identities stored under the legacy
bugs_foundcolumn. They do not count crash inputs, but they are not confirmed root-cause bug counts. - Use
known_bug_report.md,known_bug_summary.csv, andknown_bug_findings.csvfor evidence-backed known-bug hit rates; usebroken_invariants.md/broken_invariants.csvfor raw invariant identities. - Severity, exploitability, and root-cause uniqueness cannot be measured directly without richer per-bug metadata.
- Harness design still affects results; mitigate by keeping harness identical across fuzzers and reporting many runs.
Broken invariants
- Budget filter: 0.50h
- Events considered: 16 / 16
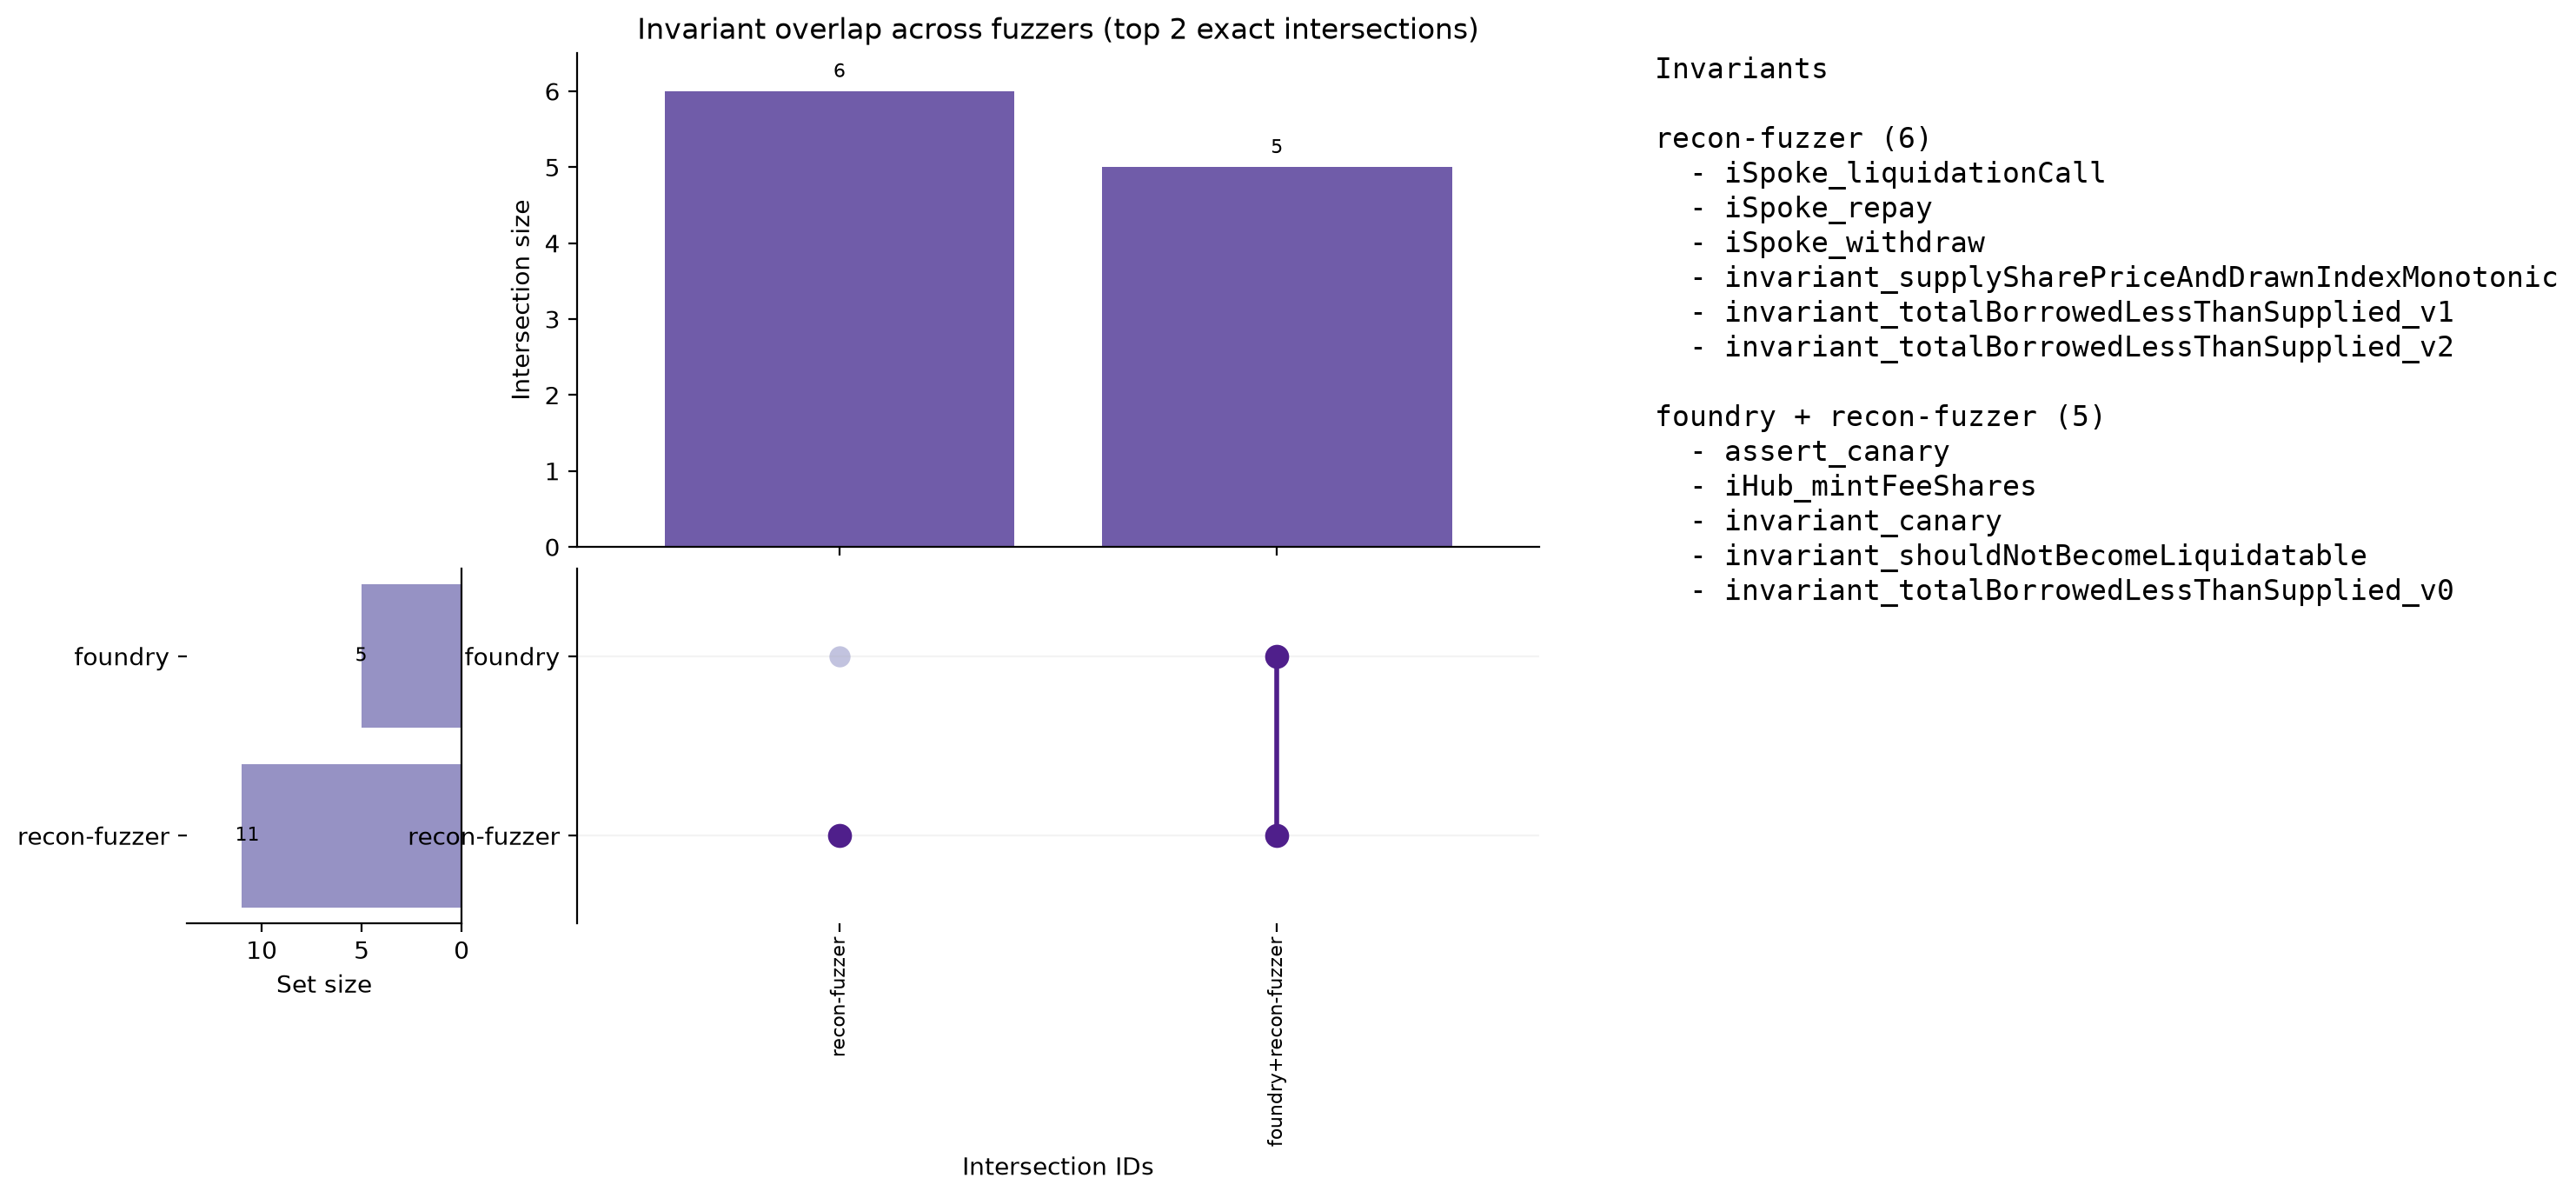
- Unique invariants: 11
Warning — trial run. This benchmark was executed with fewer than 10 instances per fuzzer and/or a time budget shorter than 24h. Results from trial runs are meant for debugging purposes and are not valid for extracting conclusions across different fuzzers.
Per-fuzzer totals
| Fuzzer | Invariants |
|---|---|
| foundry | 5 |
| recon-fuzzer | 11 |
High-level overlap
- Shared by all active fuzzers: 5
- Exclusive to
foundry: 0 - Exclusive to
recon-fuzzer: 6
Grouped invariants
Exclusive to foundry (0)
None.
Exclusive to recon-fuzzer (6)
iSpoke_liquidationCalliSpoke_repayiSpoke_withdrawinvariant_supplySharePriceAndDrawnIndexMonotonicinvariant_totalBorrowedLessThanSupplied_v1invariant_totalBorrowedLessThanSupplied_v2
Shared by all active fuzzers (5)
assert_canaryiHub_mintFeeSharesinvariant_canaryinvariant_shouldNotBecomeLiquidatableinvariant_totalBorrowedLessThanSupplied_v0
Ground-truth known-bug mapping
Ground-truth mapping was not applied.
- Reason: run commit 3f1db8ad1a756bd3ac01e6575205913d35691479 is not the evidence-pinned catalog revision 459b020058f4a65d18eb1481083b75c766340124
- Catalog:
benchmarks/known_bugs.json
No event was classified as a known bug. Raw event analysis remains available, but it must not be interpreted as a confirmed bug count.
Runner resource usage
- Budget filter: 0.50h
- Instances with metrics: 2
- Total samples: 703
Per-fuzzer medians (across instances)
| Fuzzer | Instances | CPU active avg (%) | CPU active peak (%) | Memory used avg (GiB) | Memory used peak (GiB) | Memory used avg (%) | Memory used peak (%) |
|---|---|---|---|---|---|---|---|
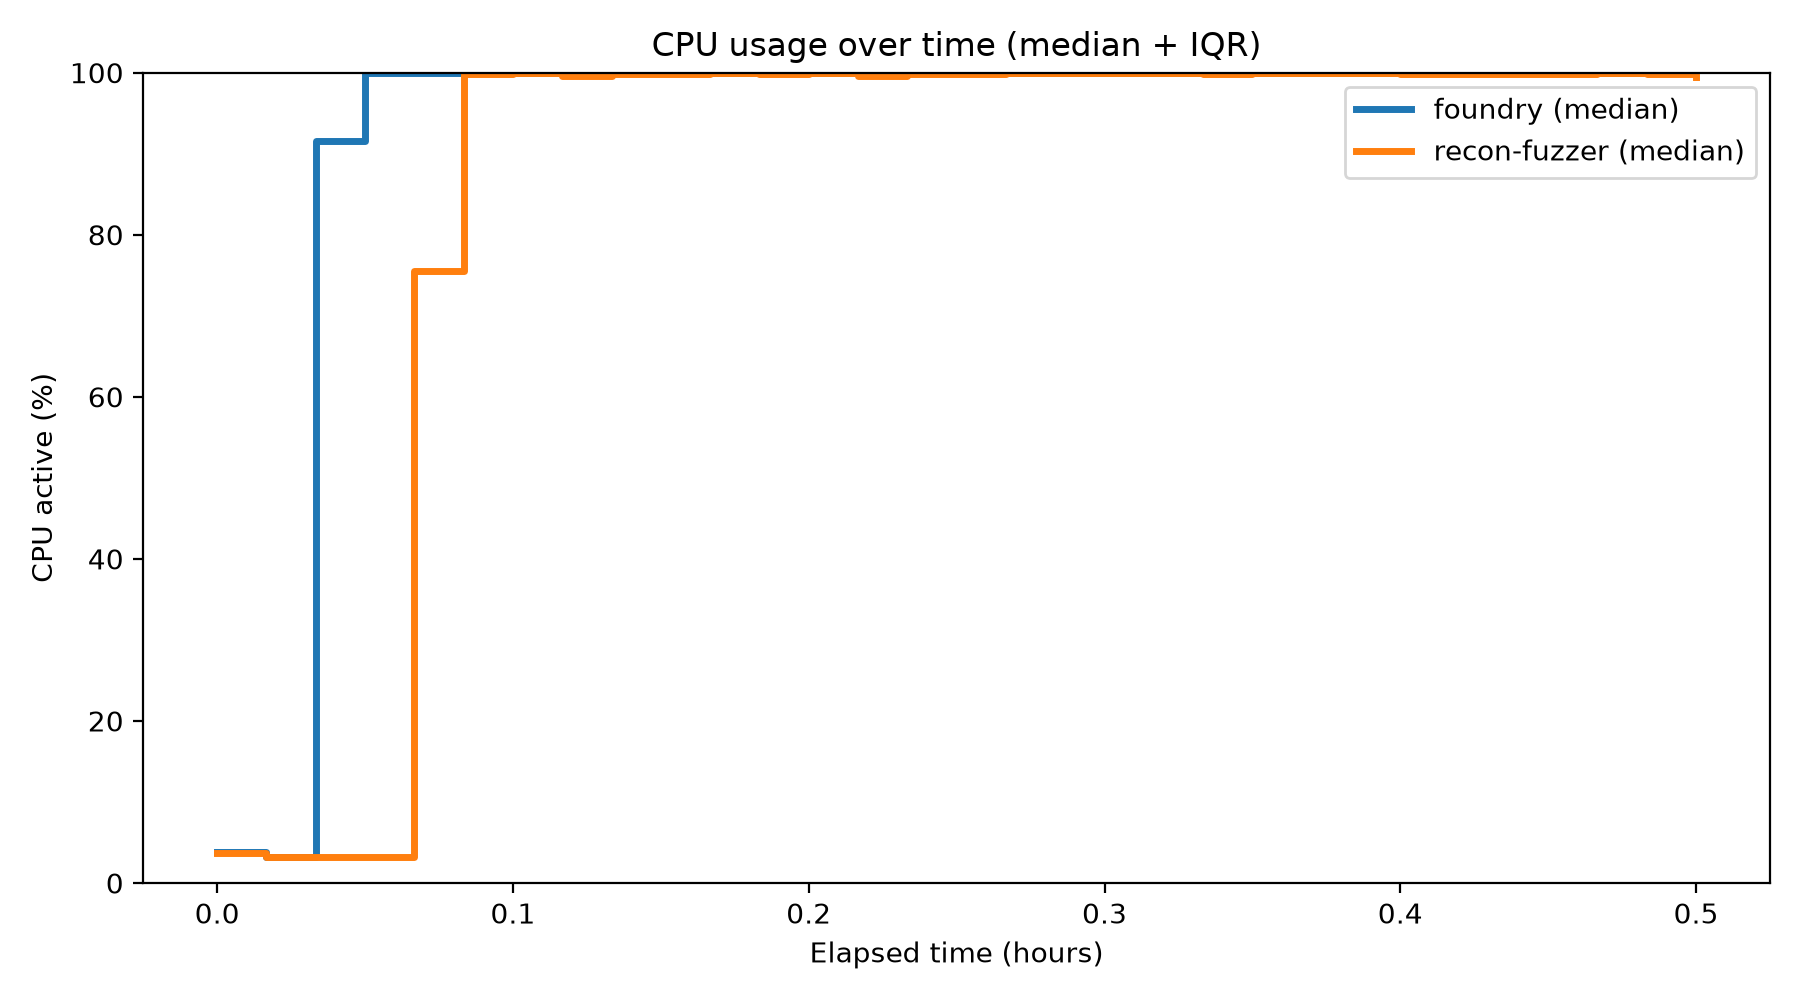
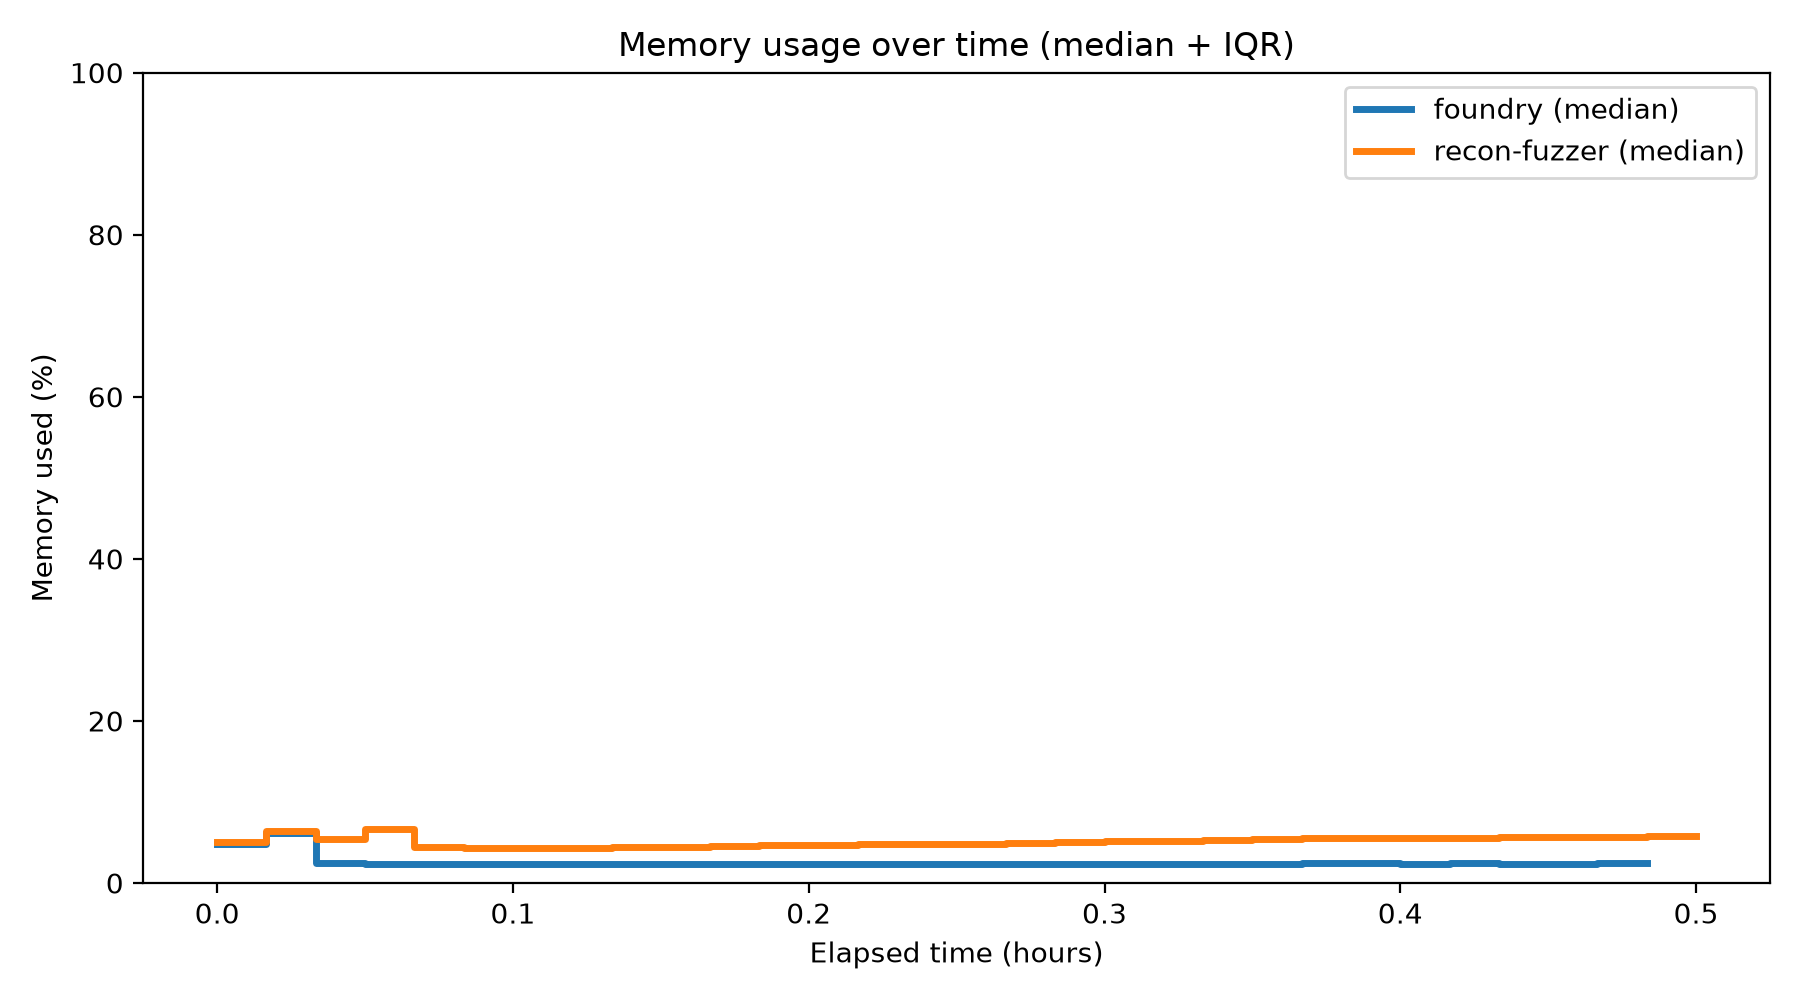
| foundry | 1 | 93.13 | 100.00 | 1.60 | 4.13 | 2.61 | 6.72 |
| recon-fuzzer | 1 | 85.89 | 100.00 | 3.17 | 4.80 | 5.15 | 7.80 |
Instance stats
| Instance | Fuzzer | Samples | Duration (h) | CPU active avg (%) | CPU active peak (%) | Memory avg (GiB) | Memory peak (GiB) | Memory avg (%) | Memory peak (%) |
|---|---|---|---|---|---|---|---|---|---|
| i-0b7b9247f741264e6-foundry-git-02c05d9 | foundry | 352 | 0.50 | 93.13 | 100.00 | 1.60 | 4.13 | 2.61 | 6.72 |
| i-0b9e7f080e2499a17-recon-v0.4.18 | recon-fuzzer | 351 | 0.50 | 85.89 | 100.00 | 3.17 | 4.80 | 5.15 | 7.80 |
Manifest
- scfuzzbench_commit:
41025567e386f1eae2a42030e4c95c0430db46a3 - target_repo_url: https://github.com/scfuzzbench/aave-v4-scfuzzbench
- target_commit:
3f1db8ad1a756bd3ac01e6575205913d35691479 - benchmark_type:
property - instance_type:
c6a.8xlarge - instances_per_fuzzer:
1 - timeout_hours:
0.5 - aws_region:
us-east-1 - ubuntu_ami_id:
ami-052355af2a014bd2c - foundry_version:
1.7.2-dev - foundry_git_repo:
https://github.com/foundry-rs/foundry - foundry_git_ref:
02c05d970d2801da0aef8b82486ce84b01ede36d - foundry_source_patch:
scfuzzbench-throughput-progress-v1@sha256:2ee9e69b77c8007c78c816eb9ca791684aa5ecede0651b63f86cdd2e055eb17e - echidna_version:
2.3.3 - medusa_version:
1.5.1 - recon_version:
0.4.18 - fuzzer_keys:
echidna, foundry, medusa, recon-fuzzer
Artifacts
Manifest (index): https://scfuzzbench-logs-185f44d6.s3.us-east-1.amazonaws.com/runs/gh-30319440655-1/a692fe4f972a7c8007558e1cecf8a08e/manifest.json
Report prefix: https://scfuzzbench-logs-185f44d6.s3.us-east-1.amazonaws.com/analysis/a692fe4f972a7c8007558e1cecf8a08e/gh-30319440655-1/
Broken invariants (Markdown): https://scfuzzbench-logs-185f44d6.s3.us-east-1.amazonaws.com/analysis/a692fe4f972a7c8007558e1cecf8a08e/gh-30319440655-1/broken_invariants.md
Broken invariants (CSV): https://scfuzzbench-logs-185f44d6.s3.us-east-1.amazonaws.com/analysis/a692fe4f972a7c8007558e1cecf8a08e/gh-30319440655-1/broken_invariants.csv
Ground-truth known bugs (Markdown): https://scfuzzbench-logs-185f44d6.s3.us-east-1.amazonaws.com/analysis/a692fe4f972a7c8007558e1cecf8a08e/gh-30319440655-1/known_bug_report.md
Ground-truth summary (CSV): https://scfuzzbench-logs-185f44d6.s3.us-east-1.amazonaws.com/analysis/a692fe4f972a7c8007558e1cecf8a08e/gh-30319440655-1/known_bug_summary.csv
Ground-truth findings (CSV): https://scfuzzbench-logs-185f44d6.s3.us-east-1.amazonaws.com/analysis/a692fe4f972a7c8007558e1cecf8a08e/gh-30319440655-1/known_bug_findings.csv
Throughput summary (CSV): https://scfuzzbench-logs-185f44d6.s3.us-east-1.amazonaws.com/analysis/a692fe4f972a7c8007558e1cecf8a08e/gh-30319440655-1/throughput_summary.csv
Progress metrics summary (CSV): https://scfuzzbench-logs-185f44d6.s3.us-east-1.amazonaws.com/analysis/a692fe4f972a7c8007558e1cecf8a08e/gh-30319440655-1/progress_metrics_summary.csv
Function selector distribution (CSV): https://scfuzzbench-logs-185f44d6.s3.us-east-1.amazonaws.com/analysis/a692fe4f972a7c8007558e1cecf8a08e/gh-30319440655-1/selector_distribution.csv
Function selector summary and health (JSON): https://scfuzzbench-logs-185f44d6.s3.us-east-1.amazonaws.com/analysis/a692fe4f972a7c8007558e1cecf8a08e/gh-30319440655-1/selector_summary.json
Runner resource usage (Markdown): https://scfuzzbench-logs-185f44d6.s3.us-east-1.amazonaws.com/analysis/a692fe4f972a7c8007558e1cecf8a08e/gh-30319440655-1/runner_resource_usage.md
Runner resource summary (CSV): https://scfuzzbench-logs-185f44d6.s3.us-east-1.amazonaws.com/analysis/a692fe4f972a7c8007558e1cecf8a08e/gh-30319440655-1/runner_resource_summary.csv
Runner resource timeseries (CSV): https://scfuzzbench-logs-185f44d6.s3.us-east-1.amazonaws.com/analysis/a692fe4f972a7c8007558e1cecf8a08e/gh-30319440655-1/runner_resource_timeseries.csv
Analysis bundle: https://scfuzzbench-logs-185f44d6.s3.us-east-1.amazonaws.com/analysis/a692fe4f972a7c8007558e1cecf8a08e/gh-30319440655-1/bundles/analysis.zip
Raw logs prefix: https://scfuzzbench-logs-185f44d6.s3.us-east-1.amazonaws.com/logs/gh-30319440655-1/a692fe4f972a7c8007558e1cecf8a08e/
Raw corpus prefix: https://scfuzzbench-logs-185f44d6.s3.us-east-1.amazonaws.com/corpus/gh-30319440655-1/a692fe4f972a7c8007558e1cecf8a08e/